💰 From Prediction to a Real Decision
OmniSTAR is only one layer of a broader system. OneRail's machine-learning models separately estimate factors including service time, lateness risk, the probability of first-attempt delivery success, and expected price ranges, and those predictions feed into the optimisation systems that determine how an order should actually be executed.
|
OmniSTAR By the Numbers
|
10x
reduction in computation time claimed for delivery calculations
|
|
12M+
drivers in OneRail's network, across 1,000+ logistics partners
|
|
$6B+
projected gross merchandise volume through OmniSTAR in Q4 2026
|
|
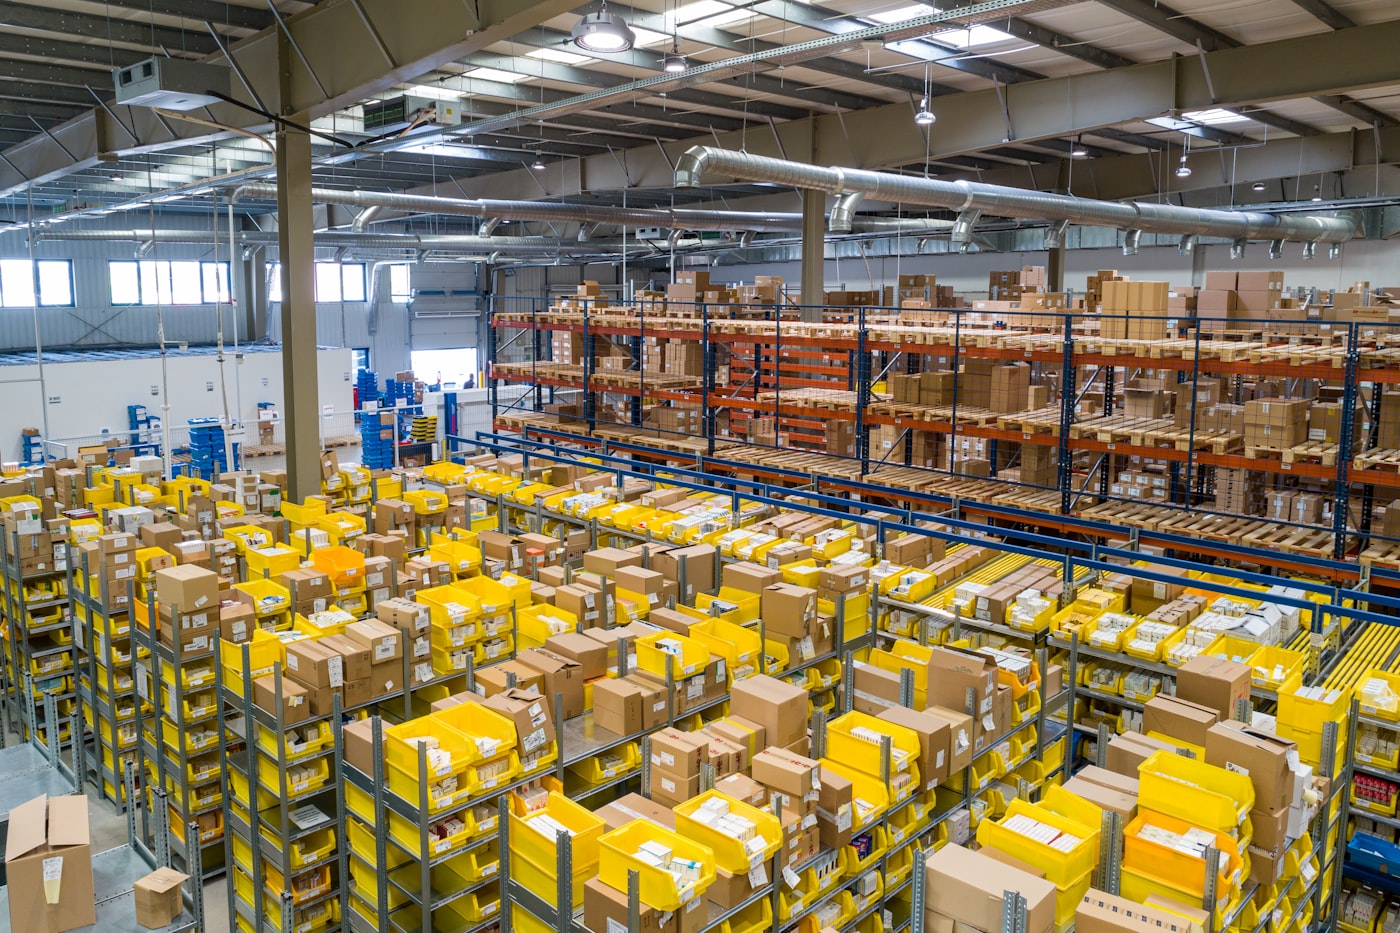
That underlying dataset is genuinely the raw material making all of this possible, OneRail's models are built on millions of deliveries across a network the company says includes more than 12 million drivers and over 1,000 logistics partners, covering pricing and delivery performance across different transportation modes. OneRail said OmniSTAR can use that information to identify delivery rules that increase costs and assess how delivery choices affect item-level profitability, not just which route is fastest, but which delivery decision is actually the most profitable one.
|

Millions of historical deliveries feed OneRail's prediction models, which then inform each real-time delivery decision.
|
📊 The Real Dollar Results So Far
OmniSTAR isn't a lab prototype, it's already deployed with selected enterprise customers, and the reported results are genuinely substantial. At US Foods, OneRail said the system identified delivery configurations that were reducing margins, including low-margin products being transported long distances using higher-cost equipment. US Foods subsequently used those findings to adjust pricing and restructure some delivery patterns.
OneRail also told CNBC that an unnamed large tire distributor using the platform achieved $40 million in run-rate savings over three years.
It's worth being fair and precise about that last figure, the customer was not identified, and the savings figure was provided by OneRail itself, not independently verified by CNBC or any third party. That's not a reason to dismiss it, but it is a reason to treat it as a company-reported claim rather than an audited result, the same standard worth applying to most vendor-reported ROI figures in enterprise technology coverage generally.
OneRail and Nvidia had worked on the project for three years before its launch, according to CNBC, including direct engagement with Nvidia's cuOpt engineering team on last-mile delivery and large-scale logistics optimisation, alongside OneRail's participation in the Nvidia Inception programme. That three-year development timeline is a useful reminder that a headline-grabbing 10x speed claim usually sits on top of a genuinely long, unglamorous engineering effort.
|
🚚 Part of a Bigger Push Into Same-Day Delivery
This launch doesn't exist in isolation, it builds on OneRail's existing infrastructure and partnerships. In March this year, FedEx launched FedEx SameDay Local in collaboration with OneRail, connecting customers to a national network of more than 1,000 delivery providers, a genuinely significant partnership that shows OneRail's technology already operating at real logistics scale before OmniSTAR's launch.
|
Worth Keeping in Mind
| ⚠️ The $40M savings figure and the identity of the customer come from OneRail, not an independent audit |
| ⚠️ OneRail says many retailers still rely on static rules or manual planning, the exact gap OmniSTAR is built to close |
| ⚠️ A 2024 review in the European Journal of Operational Research separately confirms dynamic vehicle routing and real-time re-optimisation are genuinely distinct, active research areas, not solved problems |
|
That last academic reference is worth noting, it independently corroborates that the underlying problem OmniSTAR is tackling, recalculating delivery decisions as real-world conditions shift, is a genuinely active, unsolved area of operations research, not a solved textbook problem that OneRail is simply packaging. Building a fast, workable system on top of a genuinely hard, still-evolving research area is a real technical achievement, whatever the exact scale of the dollar savings claims turns out to be.
|
OneRail's technology already underpins large-scale partnerships like FedEx SameDay Local, launched earlier this year.
|
🧠 AI Spotlight Analysis
This story is a genuinely good illustration of a broader pattern in enterprise AI that gets far less attention than flashy chatbot demos, unglamorous, backend optimization work that quietly compounds into real, measurable savings at scale. Nobody's going to be impressed watching a delivery routing calculation happen faster, but for a company shipping millions of packages, the difference between a 20-minute and a 2-minute decision genuinely determines whether AI-assisted optimization can run continuously throughout a live operating day, or only once at the start of it.
The stateless design of cuOpt is also a useful reminder that "AI" in a logistics context often means something quite different from a conversational chatbot, no memory, no ongoing context, just a very fast, very capable solver that gets re-asked the same fundamental question every time the world changes around it. That's a genuinely different, and in this case more appropriate, architecture than the large language models most people associate with the term AI today.
💬 Quote of the Week
"If you don't have the ability to make lightning-fast decisions, you're giving up margin. Last-mile fulfilment is expensive."
— Catania, in an interview with CNBC
That line is really the whole business case in a sentence. Last-mile delivery is one of the most expensive parts of retail logistics precisely because it's fragmented across so many small, individually cheap-seeming decisions, which mode, which driver, which route. Making each of those decisions faster and slightly better, multiplied across millions of orders, is exactly where genuinely large aggregate savings tend to hide.
|
💡 Final Thoughts
OmniSTAR is a genuinely solid example of AI infrastructure doing exactly the kind of unglamorous, high-leverage work that rarely makes for exciting headlines but quietly reshapes how an entire industry operates. Speed isn't a nice-to-have feature here, it's the entire mechanism that makes the optimization usable inside a live, constantly changing operation rather than a nightly batch job.
The honest caveat worth holding onto is that the headline dollar figures, the $40 million savings claim in particular, come from OneRail itself, not an independent audit. That doesn't make them false, but it's a reasonable, healthy habit to apply the same scrutiny to vendor-reported AI ROI numbers here as anywhere else in enterprise technology reporting.
Does the speed of a decision matter more to you than its theoretical perfection, in your own work? Hit reply, we read every response.
|
🔗 Sources and Further Reading
|
❤️ Enjoying AI Spotlight?
If today's edition helped you see how AI quietly reshapes something as ordinary as a delivery route, consider sharing it with a colleague, founder, or friend interested in technology.
Share AI Spotlight →
|
|
|
Thanks for reading AI Spotlight.
Our mission is simple: deliver clear, trustworthy, and actionable AI insights that help professionals stay ahead without the hype.
|
|